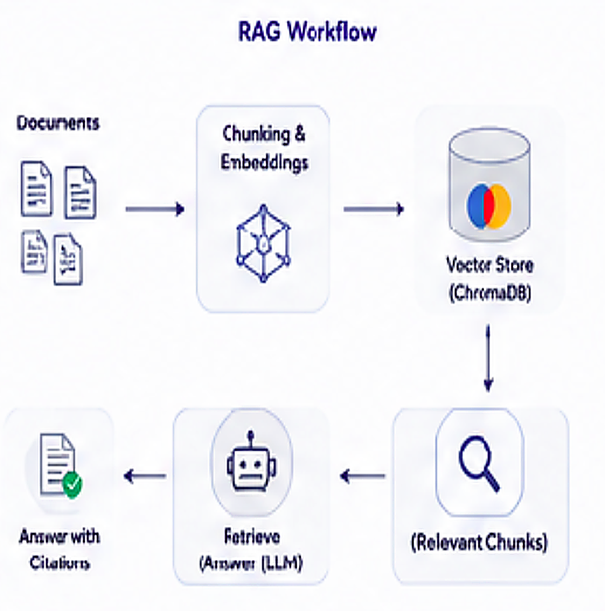
DocuSense is an intelligent document assistant built on AWS that retrieves and grounds every answer strictly in an organization's own knowledge base, using retrieval, context-expansion, and summarization tools to deliver accurate, source-cited responses.
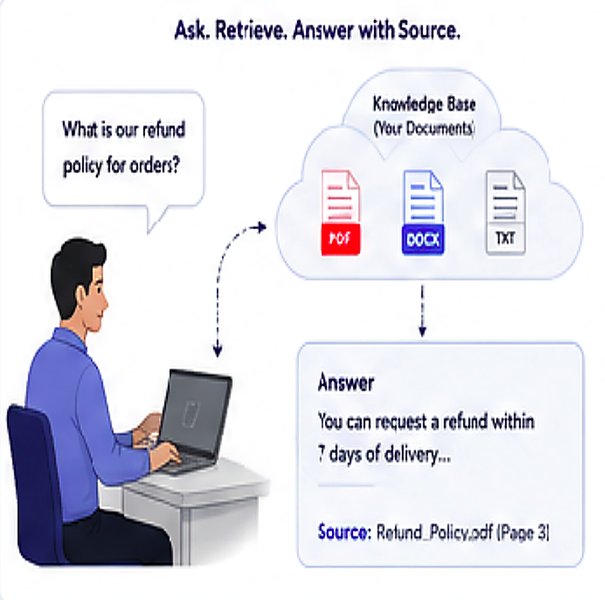
The challenge was building a platform that could accurately find the most relevant documents for any user query in real time — dynamically choosing between retrieval, context expansion, and summarization tools — while never generating an answer that wasn't grounded in the actual source material.
The system always searches the knowledge base before generating a response, trusting a reranked relevance order rather than raw vector scores. When a retrieved chunk references a parent document, a dedicated tool fetches fuller context; when content is too long, a summarizer condenses it. Every answer is required to cite its source document, and the model is explicitly instructed to say so rather than hallucinate when no relevant information exists.
We built the ingestion and parsing layer using PyMuPDF, stored embeddings in ChromaDB for fast semantic search, and deployed the retrieval and serving layer on AWS EC2 with FastAPI — designing every step around a "retrieve first, ground always" principle.
DocuSense turns a static knowledge base into a responsive, trustworthy assistant that never answers beyond what it can verify.
Enhancing Knowledge Retrieval Through Grounded AI DocuSense combines retrieval accuracy with AWS-grade scalability to keep answers fast and trustworthy.
“The moment a RAG system answers from memory instead of your documents, you've lost the trust that makes it useful.” — Manu Sharma, CEO
Blending Retrieval Intelligence with AWS Scalability DocuSense was designed so every response a user sees can be traced directly back to its source.
Delivering Trustworthy, Source-Grounded Answers DocuSense proved that grounding and speed aren't a trade-off when the architecture is built right.